
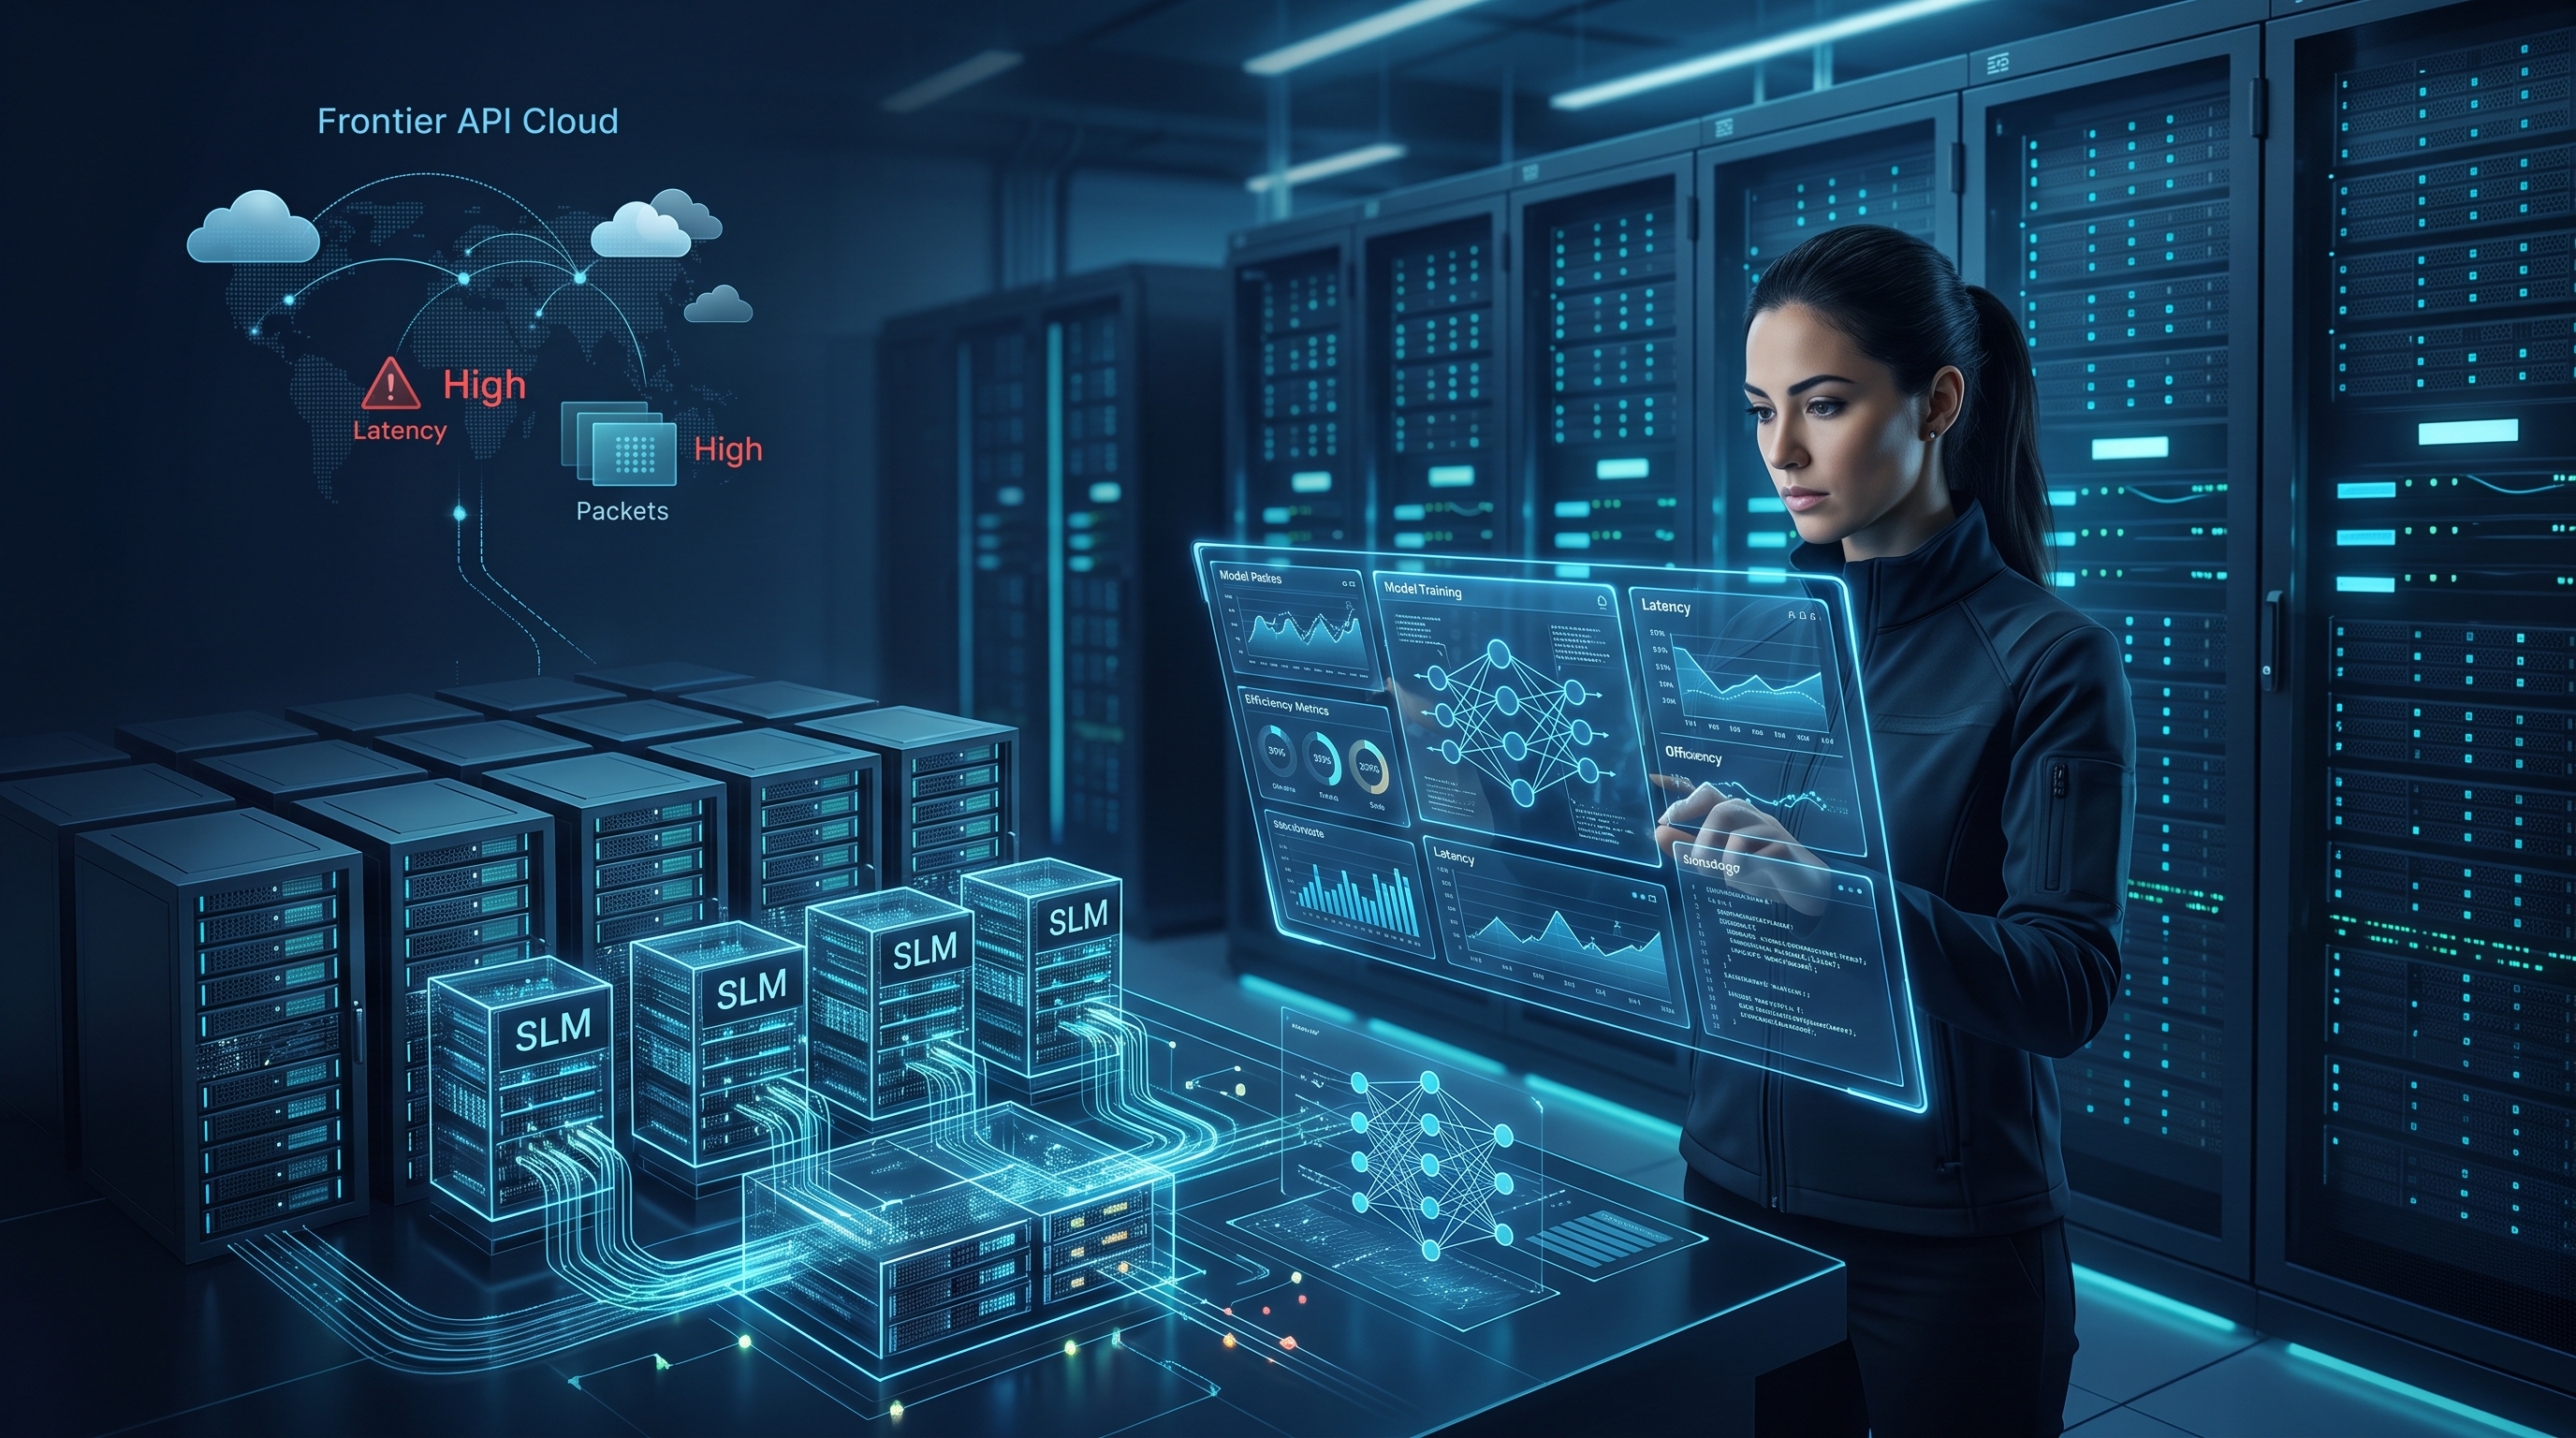
The 2026 Reality: Why Cloud APIs No Longer Scale
I spent two decades at JPMorgan Chase, Deutsche Bank, and Morgan Stanley watching financial institutions chase the "bigger is better" paradigm. We bought the most expensive cloud GPU instances and routed millions of tokens through frontier APIs like GPT-4o or Claude Sonnet. The results were predictable: latency spiked during peak market hours, costs ballooned unpredictably, and data privacy teams remained perpetually anxious.
By 2026, that model is broken for enterprise workloads. The target keyword "small language models on-prem enterprise 2026" isn’t just a trend; it’s a structural shift in AI infrastructure. We are no longer using Large Language Models (LLMs) for everything. We are using them for what they are good at: complex reasoning, creative generation, and ambiguous query resolution. For everything else—entity extraction, classification, summarization, and structured data formatting—Small Language Models (SLMs) are not just cheaper; they are technically superior.
The math is simple. A 7B parameter model, quantized to 4-bit precision, fits comfortably into the VRAM of a single NVIDIA L40S. Inference latency drops from the 2-5 seconds typical of cloud API calls to under 50 milliseconds. For an enterprise processing 10,000 documents a day, that is the difference between a batch job and a real-time stream.
Latency, Cost, and the Sovereignty Imperative
Let’s talk about the three pillars that make on-prem SLMs indispensable in 2026: latency, cost, and sovereignty.
First, latency. In high-frequency trading or real-time fraud detection, every millisecond counts. Cloud APIs add network hops, TLS handshakes, and queue wait times. An on-prem SLM running on Kubernetes eliminates the network hop entirely. You are not paying for the convenience of abstraction; you are paying for the speed of execution.
Second, cost. Cloud API costs are variable and opaque. You pay per token, and tokens add up. A quantized SLM running on hardware you already own has a fixed cost. The marginal cost of inference approaches zero. For routine tasks, the cost reduction is often over 90% compared to frontier APIs. This is not a theoretical savings; it is a balance sheet reality.
Third, sovereignty. In regulated industries, data cannot leave the premises. Period. When you send PII or proprietary financial data to a cloud API, you are trusting a third party with your most sensitive assets. On-prem SLMs keep inference within your VPC. You control the network, the storage, and the compute. This is non-negotiable for banks, healthcare providers, and government agencies.
Architectural Patterns for SLM Deployment
Deploying SLMs on-prem is not just about buying GPUs. It requires a shift in architectural thinking. We are moving from a monolithic AI strategy to a composite AI approach.
Here is the pattern I recommend for enterprise SLM deployment:
- Model Selection: Stick to models with 3B to 7B parameters. Examples include Llama 3.1 8B, Mistral 7B, or Phi-3. These models have been heavily optimized for instruction following and structured output.
- Quantization: Use 4-bit quantization (Q4_K_M) to maximize throughput. This reduces memory footprint by 75% with negligible accuracy loss for most enterprise tasks.
- Orchestration: Use Kubernetes operators like Kserve or Ray Serve. These tools handle model loading, scaling, and health checks automatically. You treat the SLM like any other microservice.
- Gateway: Implement a routing layer that directs simple requests to the SLM and complex, ambiguous requests to the cloud LLM. This hybrid approach captures the best of both worlds.
This pattern ensures that you are not locking yourself into a single vendor. You have the flexibility to swap models as the ecosystem evolves.
Agentic AI and the Need for Determinism
The rise of Agentic AI has further solidified the case for SLMs. Agents require deterministic, low-latency responses to function effectively. A heavy LLM with high variance in output is a liability in an automated workflow. You need an agent that can reliably extract JSON from a PDF, not one that hallucinates a schema.
SLMs are ideal for the "doer" role in agentic architectures. They are fast, predictable, and cheap. The "thinker" role—the complex reasoning agent—can still be a cloud LLM, but it should be invoked sparingly.
For more on how to govern these agents, read my post on AI Agent Governance in Enterprise Compliance 2026. You need strict guardrails, especially when agents are making autonomous decisions based on SLM outputs.
Implementation: From Prototype to Production
I have seen many enterprises fail at SLM deployment because they treat it like an IT project rather than an engineering one. Here is how to get it right.
First, define your success metrics. Are you optimizing for latency? Throughput? Accuracy? For most SLM use cases, accuracy is secondary to speed and cost. A 95% accurate response in 50ms is better than a 99% accurate response in 5 seconds.
Second, build evaluation pipelines. You cannot improve what you cannot measure. Use tools like LangSmith or custom benchmarks to test your SLMs against your specific datasets. For detailed guidance on evaluation, see AI Agent Evaluation and Benchmarking in Enterprise 2026.
Third, monitor everything. Use Prometheus and Grafana to track inference latency, error rates, and GPU utilization. If an SLM starts to degrade, you need to know immediately.
Frequently Asked Questions
Q: Can SLMs replace LLMs entirely?
A: No. SLMs excel at structured, deterministic tasks. They struggle with open-ended creative writing, complex multi-step reasoning, and nuanced language understanding. The best architecture is hybrid: SLMs for the heavy lifting of routine tasks, LLMs for the complex exceptions.
Q: What is the minimum hardware required for a 7B SLM?
A: For a 7B model with 4-bit quantization, you need at least 8GB of VRAM. However, for production throughput, I recommend NVIDIA L40S or A100 GPUs with 24GB+ VRAM. This allows for batch processing and concurrent requests.
Q: How do I handle model updates on-prem?
A: Treat models as immutable artifacts. Use CI/CD pipelines to deploy new model versions. When you need to update, deploy the new version alongside the old one, shift traffic gradually, and then retire the old version. This minimizes downtime and risk.
Q: Is on-prem SLM deployment more complex than cloud APIs?
A: Initially, yes. You have to manage hardware, drivers, and orchestration. But long-term, it is simpler. You have full control over your stack. You are not dependent on API rate limits, pricing changes, or vendor lock-in. For enterprises with significant AI workloads, the complexity is a worthwhile trade-off.