
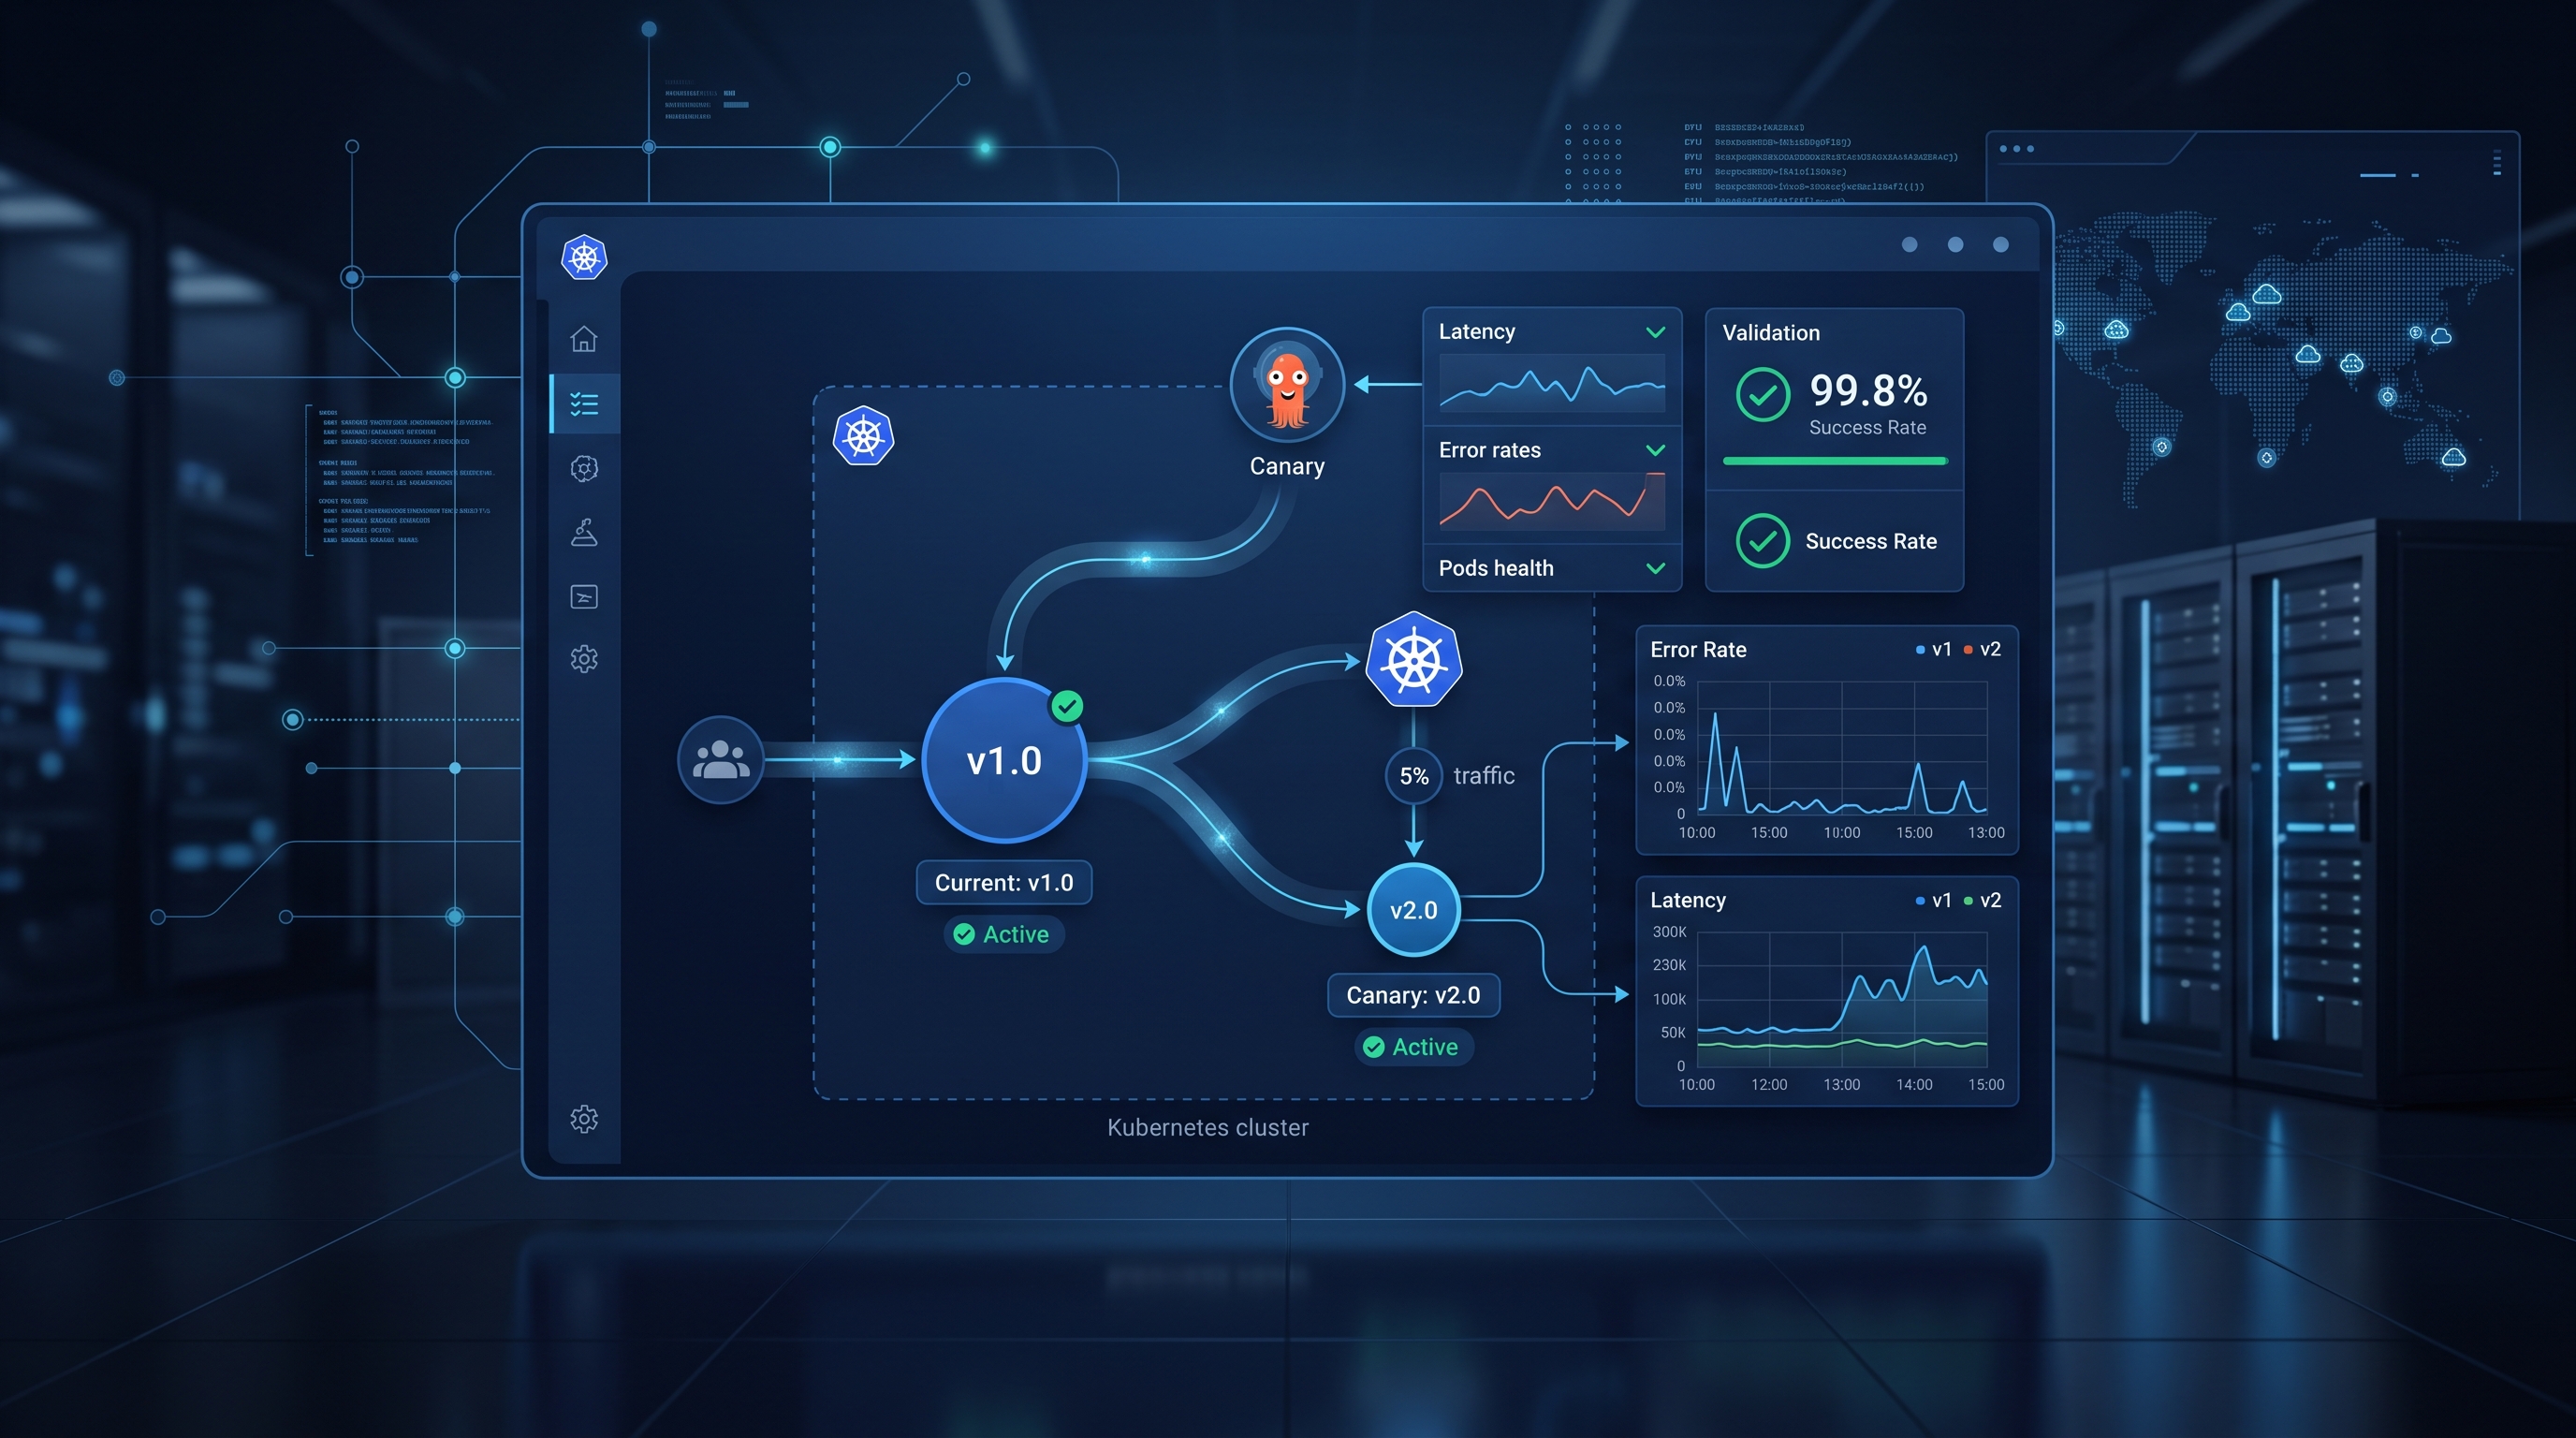
The Evolution of Deployment Safety
After 25 years in enterprise banking infrastructure, from JPMorgan Chase to Deutsche Bank, I have seen the same cycle repeat: code moves faster than the platform can safely validate it. We stopped relying on "hope and prayer" deployments years ago. Today, in 2026, the standard for enterprise Kubernetes is not just "deployment," but "progressive delivery." And within that ecosystem, Argo Rollouts is the engine that matters.
Many teams still treat Kubernetes Deployments as a black box. They apply a YAML, wait for the pods to spin up, and cross their fingers. This is how you create outages. Progressive delivery is not a buzzword; it is a risk mitigation strategy. It allows you to shift traffic to new versions incrementally, validate against real user behavior, and roll back before the majority of your users are impacted.
Why Argo Rollouts Beats Static Deployments
Kubernetes native Deployments are static. They do not understand traffic percentages, health checks beyond liveness probes, or complex routing rules. Argo Rollouts introduces the Rollout custom resource, which acts as a drop-in replacement for the Deployment but adds a control plane that understands progressive delivery strategies.
The core advantage is the separation of the "desired state" from the "execution state." You declare that 10% of traffic should go to v2, and the Rollout controller manages the ReplicaSets and traffic shifting to achieve that state. This is critical for enterprises where a single failed deployment can cost millions in downtime.
If you are still debating between manual Jenkins pipelines and declarative GitOps, you should read my analysis on argo-cd-vs-jenkins-2026. While Argo CD syncs the state, Argo Rollouts executes the safe transition. They are complementary, not competitive.
Configuring the Canary Strategy
The "canary" strategy is the most common pattern in enterprise environments. It involves running two versions of your application simultaneously: the stable version (current) and the canary version (new). The traffic is shifted gradually from stable to canary based on analysis results.
Here is a concrete example of a basic Canary configuration. Note the analysis block, which is where the intelligence lives.
apiVersion: argoproj.io/v1alpha1
kind: Rollout
metadata:
  name: my-app
spec:
  replicas: 10
  selector:
    matchLabels:
      app: my-app
  template:
    metadata:
      labels:
        app: my-app
    spec:
      containers:
      - name: my-app
        image: registry/my-app:v2
        ports:
        - containerPort: 8080
  strategy:
    canary:
      steps:
      - setCanaryScale:
          weight: 10
      - analyze:
          revisionHistoryLimit: 2
          matchingRules:
          - metric:
              name: error-rate
              successCondition: result[0] < 1
              interval: 30s
In this configuration, the first step scales the canary to 10% weight. The second step triggers an analysis run. If the error rate metric remains below 1% for 30 seconds, the rollout proceeds. If it spikes, the controller automatically rolls back. This is not magic; it is rigorous engineering.
The Critical Role of Service Meshes
You cannot do progressive delivery effectively without a service mesh like Istio or Linkerd. Argo Rollouts relies on the mesh to manipulate HTTP headers, weights, and routing rules. The Rollout controller talks to the mesh sidecars to adjust the traffic distribution.
This integration allows for advanced patterns like header-based canarying. You can route specific user IDs or internal QA teams to the canary version while production traffic remains untouched. This is essential for A/B testing in regulated environments where you cannot risk exposing untested code to the general public.
For a deeper dive into the architectural differences between blue-green and canary approaches, see blue-green-versus-canary-deployment-2026. Blue-green is great for zero-downtime, but canary provides the feedback loop necessary for continuous improvement.
Analysis and Observability
The success of your progressive delivery strategy depends entirely on your analysis templates. These are external services that Argo Rollouts queries to determine if the canary is healthy. Common metrics include:
- Error Rates: The percentage of HTTP 5xx responses.
- Latency P99: The 99th percentile response time.
- Business Metrics: Conversion rates, checkout completions, or API throughput.
If you do not have these metrics exposed, you are flying blind. I recommend integrating with Prometheus and Grafana. Your analysis template should query Prometheus, and the result should be a simple boolean or numeric value. The Rollout controller then makes the go/no-go decision based on this data.
Frequently Asked Questions
Q: Can I use Argo Rollouts with Helm? A: Yes. Argo Rollouts integrates seamlessly with Helm charts. You can define the Rollout resource within a Helm chart and manage it through Argo CD. This keeps your entire infrastructure as code, maintaining the GitOps principle.
Q: How do I handle database migrations during a canary? A: Database migrations are the hardest part of progressive delivery. The best practice is to make migrations backward-compatible. Your new code should be able to read from the old schema while writing to the new one. Alternatively, use feature flags to disable new database-dependent features in the canary until the migration is fully verified.
Q: Is Argo Rollouts production-ready for banking systems? A: Absolutely. Argo Rollouts is CNCF graduated and widely used in financial institutions. However, you must configure it correctly. Ensure you have proper RBAC, network policies, and audit logging. The tool is mature; your implementation must be secure.
Q: What happens if the analysis fails? A: If the analysis fails, the Rollout controller pauses the rollout. It does not automatically abort unless you configure an abort condition. You can then investigate the metrics, fix the issue, and either resume the rollout or manually abort it. This pause gives your team time to react without causing a full outage.