
The Deployment Strategy War is Over
For the last decade, the "Blue-Green vs. Canary" debate has been the favorite topic of junior engineers trying to sound authoritative in stand-ups. I spent 25 years at institutions like JPMorgan Chase and Deutsche Bank, where a failed deployment meant more than just a red build ticket—it meant regulatory scrutiny and millions in potential exposure. In 2026, the debate isn't about which is "better." It's about which fits your risk appetite, your infrastructure budget, and your observability maturity.
The truth is, most enterprises don't pick one. They use Blue-Green for major platform upgrades and Canary for feature toggles. But you need to understand the mechanics of blue green versus canary deployment 2026 to stop guessing and start engineering with intent. Let’s cut through the hype and look at the concrete realities of running this in production.
Blue-Green: The Safety Net for Critical Infrastructure
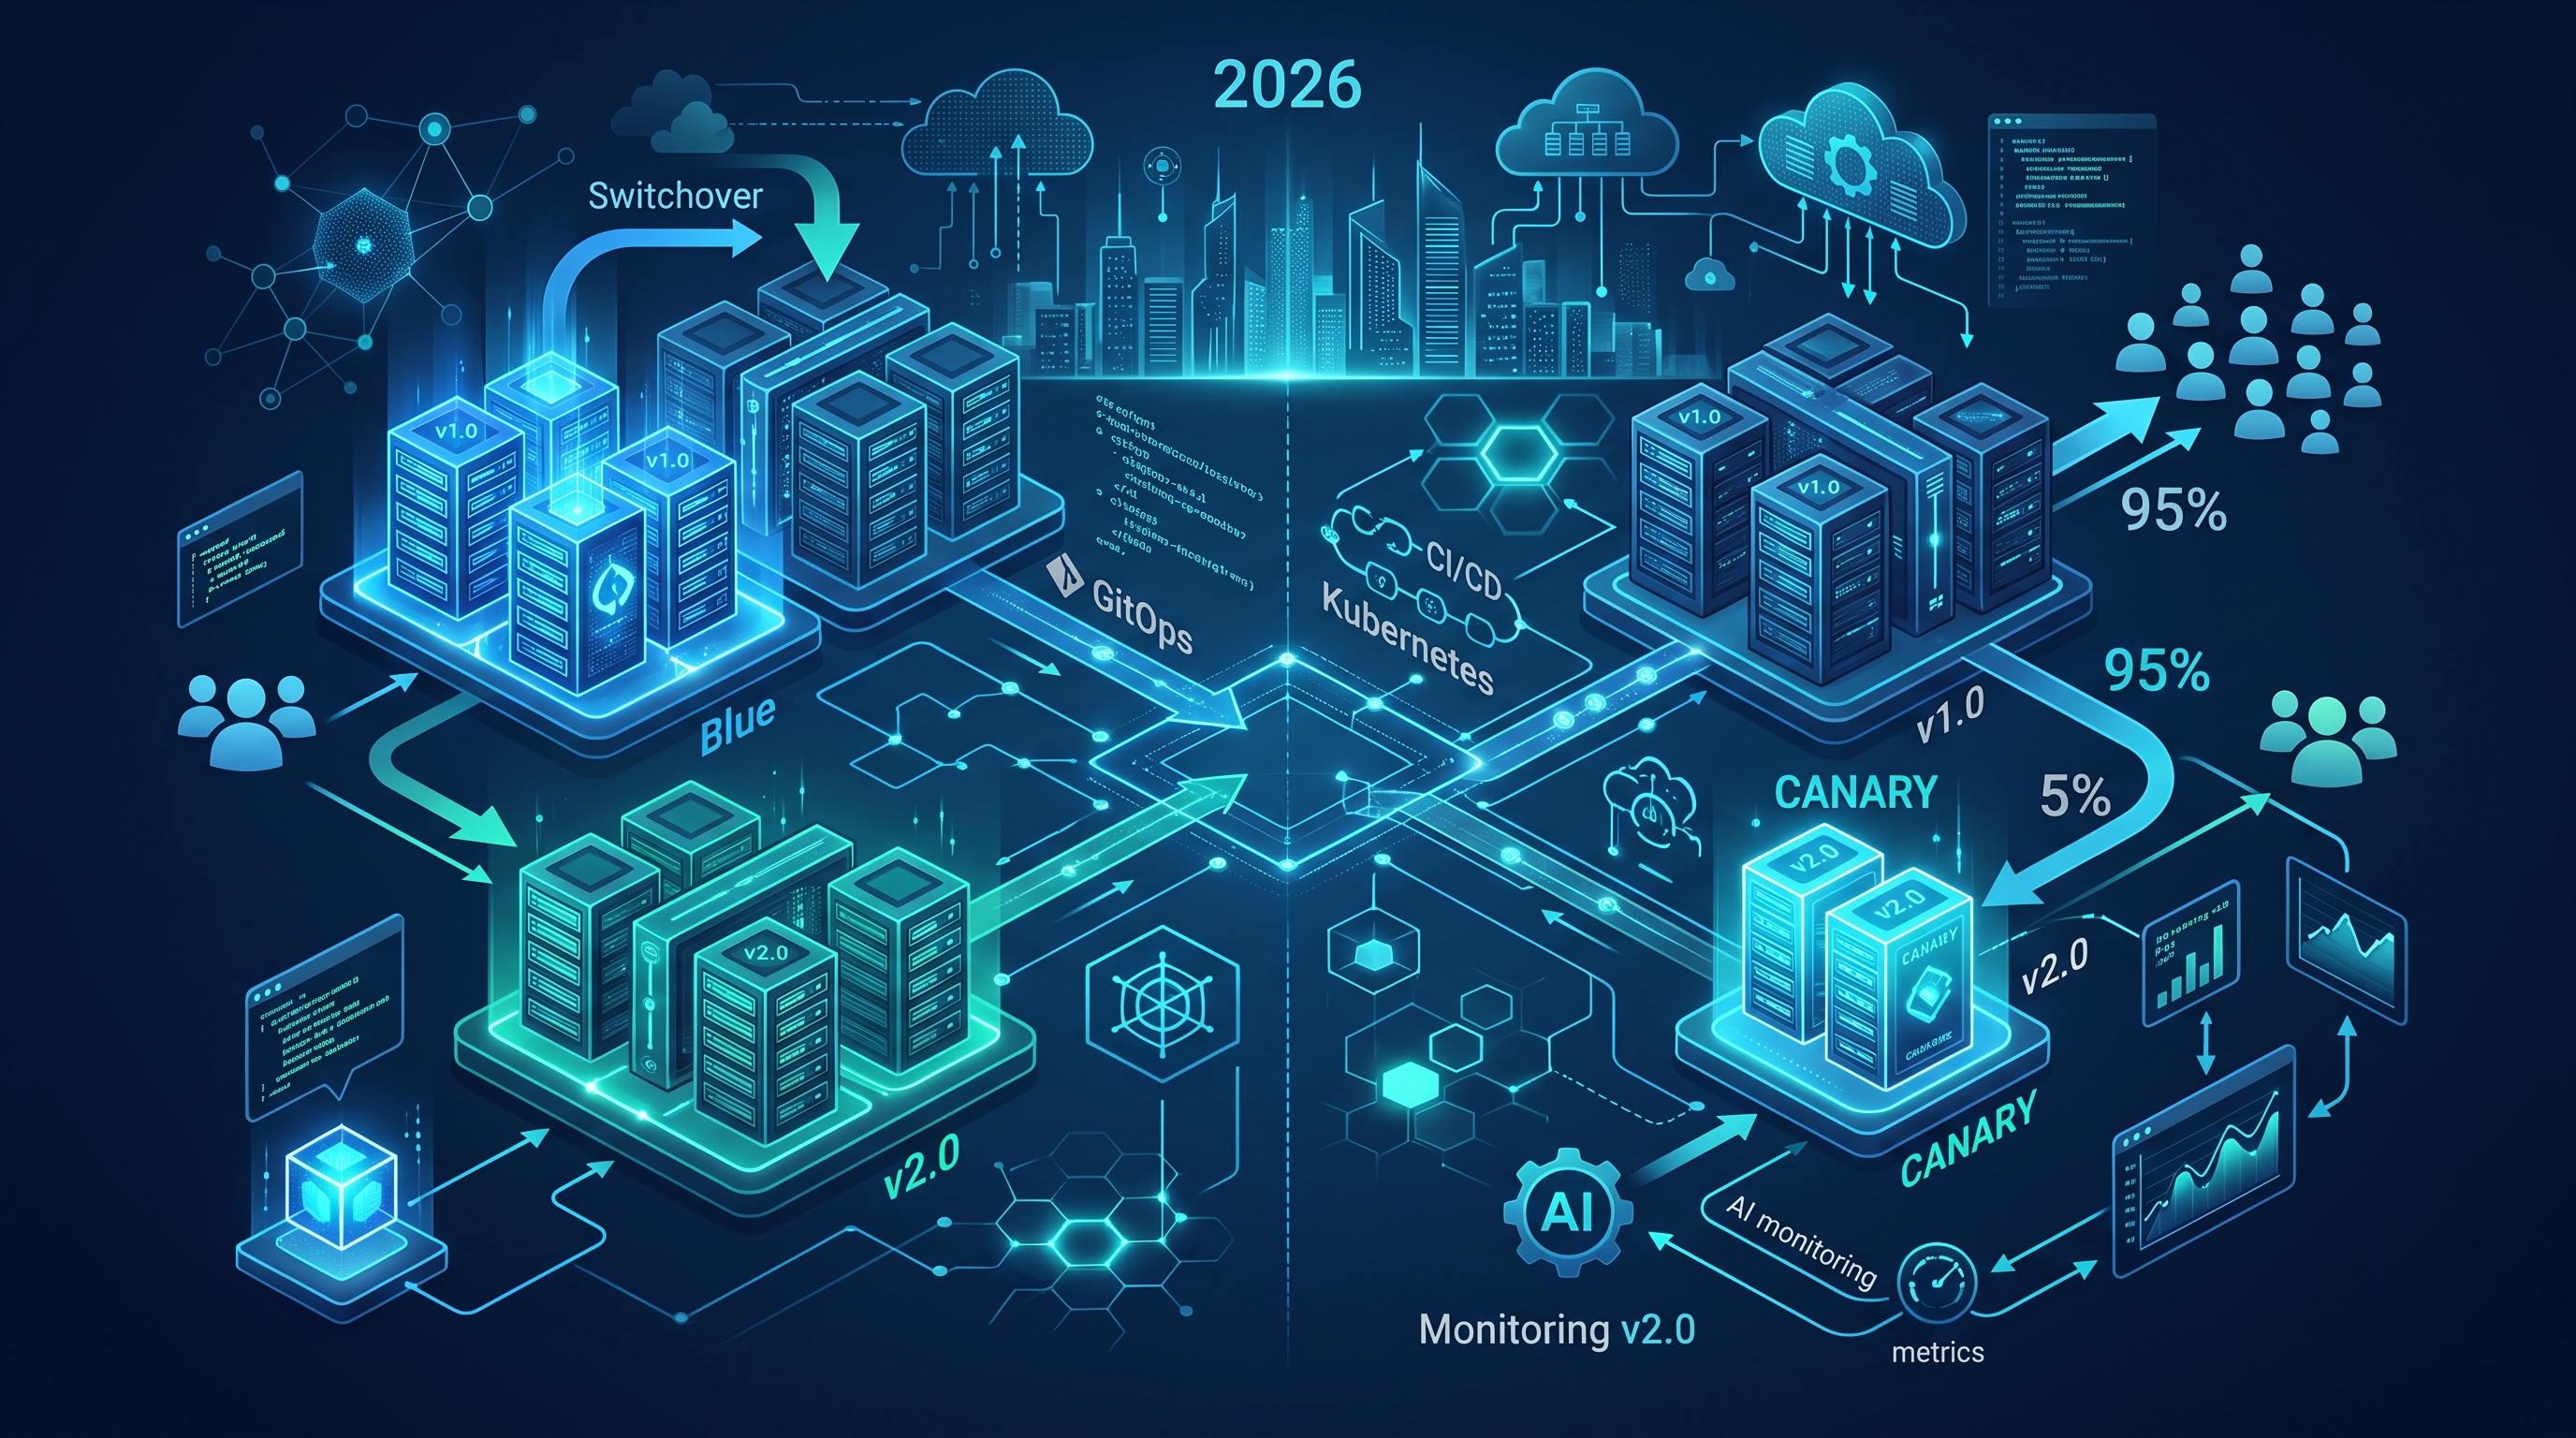
Blue-Green deployment is the enterprise workhorse. It is not glamorous, but it is incredibly robust. The concept is simple: you maintain two identical environments. "Blue" is live, handling production traffic. "Green" is the staging mirror of your next release. Once Green passes all checks, you flip a switch—usually a load balancer or a service mesh rule—to point all traffic to Green.
The primary advantage is the speed of rollback. If Green fails, you flip the switch back to Blue in milliseconds. There is no gradual traffic shifting to manage, no complex analysis windows to wait for. For core banking ledgers or authentication services, this speed is a feature, not a bug.
However, the cost is real. You are paying for double the compute resources during the deployment window. In a Kubernetes cluster, this means running two sets of stateless pods and potentially duplicating stateful components depending on your architecture. If you are running on AWS or Azure, your bill will reflect this 100% increase in resource allocation for the duration of the switch.
Blue-Green also suffers from "stale state" issues. If your application relies on in-memory caches or local disk state, flipping the entire fleet at once can cause a thundering herd problem. You have to ensure your application is truly stateless or that your state management (like Redis or PostgreSQL) can handle the sudden shift in connection patterns.
Canary: The Gradual Release of Confidence
Canary deployment is about risk mitigation through observation. Instead of flipping a switch, you route a small percentage of traffic—say 1% or 5%—to the new version. You monitor key metrics: error rates, latency, CPU usage, and business-specific KPIs. If the metrics hold steady, you gradually increase the traffic to 10%, 20%, and eventually 100%.
This strategy is superior for complex microservices architectures where a bug might be subtle. A 5% error rate spike might be lost in the noise of a full rollout, but in a canary, it’s a glaring red flag. It allows you to catch regressions before they impact your entire user base.
The downside? It requires sophisticated observability. You cannot do a canary deployment effectively without a robust monitoring stack. If you are still relying on basic logging without distributed tracing, you are blind during the canary phase. You need tools that can correlate traffic shifts with performance metrics in real-time.
Furthermore, canary deployments take time. A typical rollout might take 30 to 60 minutes to reach full capacity. If you have a deployment window constraint—like a maintenance window that closes at 2 AM—you might not have enough time to run a full canary analysis. In those cases, Blue-Green is the only viable option.
The 2026 Landscape: Service Meshes and Automation
In 2026, the manual configuration of routing rules is dead. We use service meshes like Istio or Linkerd to handle the heavy lifting. These tools allow us to define traffic splitting rules declaratively. For example, you can define a VirtualService that routes 95% of traffic to the stable version and 5% to the canary, with automatic promotion based on HTTP status codes.
This automation changes the game. It allows us to integrate canary analysis directly into our CI/CD pipelines. Tools like Flagger or Argo Rollouts can automatically analyze Prometheus metrics and promote the canary if it passes the defined thresholds. This reduces the human element of "should I promote this?" to a simple "did the tests pass?"
When combined with MLOps model deployment strategies, this becomes even more critical. ML models are probabilistic, not deterministic. A canary deployment allows you to test model drift and prediction accuracy on a small subset of users before exposing the entire database to potential hallucinations or bias.
When to Choose Which
So, how do you decide? Here is my practical framework based on two decades of enterprise experience:
- Choose Blue-Green when: You are deploying a major version upgrade, you have strict rollback requirements (sub-second), or your application is stateful and difficult to shard. Also use this when you lack the observability maturity for canary analysis.
- Choose Canary when: You are deploying feature changes, you have high-traffic services where even a 1% error rate is unacceptable, and you have robust metrics pipelines. This is ideal for UI changes, API endpoints, and non-critical microservices.
It is also worth noting that for Agentic AI deployments, the stakes are different. If an AI agent starts hallucinating or sending incorrect emails, a Blue-Green switch stops it immediately. A Canary might let it continue for minutes, causing reputational damage. Therefore, for high-risk AI agents, I often default to Blue-Green with a strict pre-flight check.
Frequently Asked Questions
Can I use Blue-Green and Canary together?
Yes, and many enterprises do. You can use Blue-Green for the underlying platform infrastructure (like Kubernetes control plane upgrades) and Canary for the application layer. This hybrid approach gives you the safety of Blue-Green for the platform and the granularity of Canary for your business logic. It requires careful orchestration but offers the best of both worlds.
How much traffic should I send to a Canary in 2026?
There is no one-size-fits-all answer, but 1% to 5% is a common starting point. For high-traffic services, start at 1%. For lower-traffic services, you might start at 5% to get statistically significant data faster. The key is to start low and increase gradually based on your error budget. If your error budget allows, you can increase faster. If you are risk-averse, stay low longer.
Is Blue-Green deployment really that expensive?
It depends on your cloud provider and architecture. In a pure Kubernetes environment, you are paying for the pods. If you use spot instances for your Blue-Green environments, you can reduce costs significantly. However, you must account for the overhead of maintaining two sets of environments. For small teams, the cost might be prohibitive. For large enterprises, it is a necessary insurance policy.
What tools do I need for a successful Canary deployment?
You need three things: a service mesh for traffic routing, a monitoring system for metrics collection, and an automation tool for promotion. Popular choices include Istio for routing, Prometheus and Grafana for metrics, and Argo Rollouts or Flagger for automation. If you are dealing with FastAPI-based AI agents, ensure your monitoring stack can handle the specific latency and throughput characteristics of your inference endpoints.