
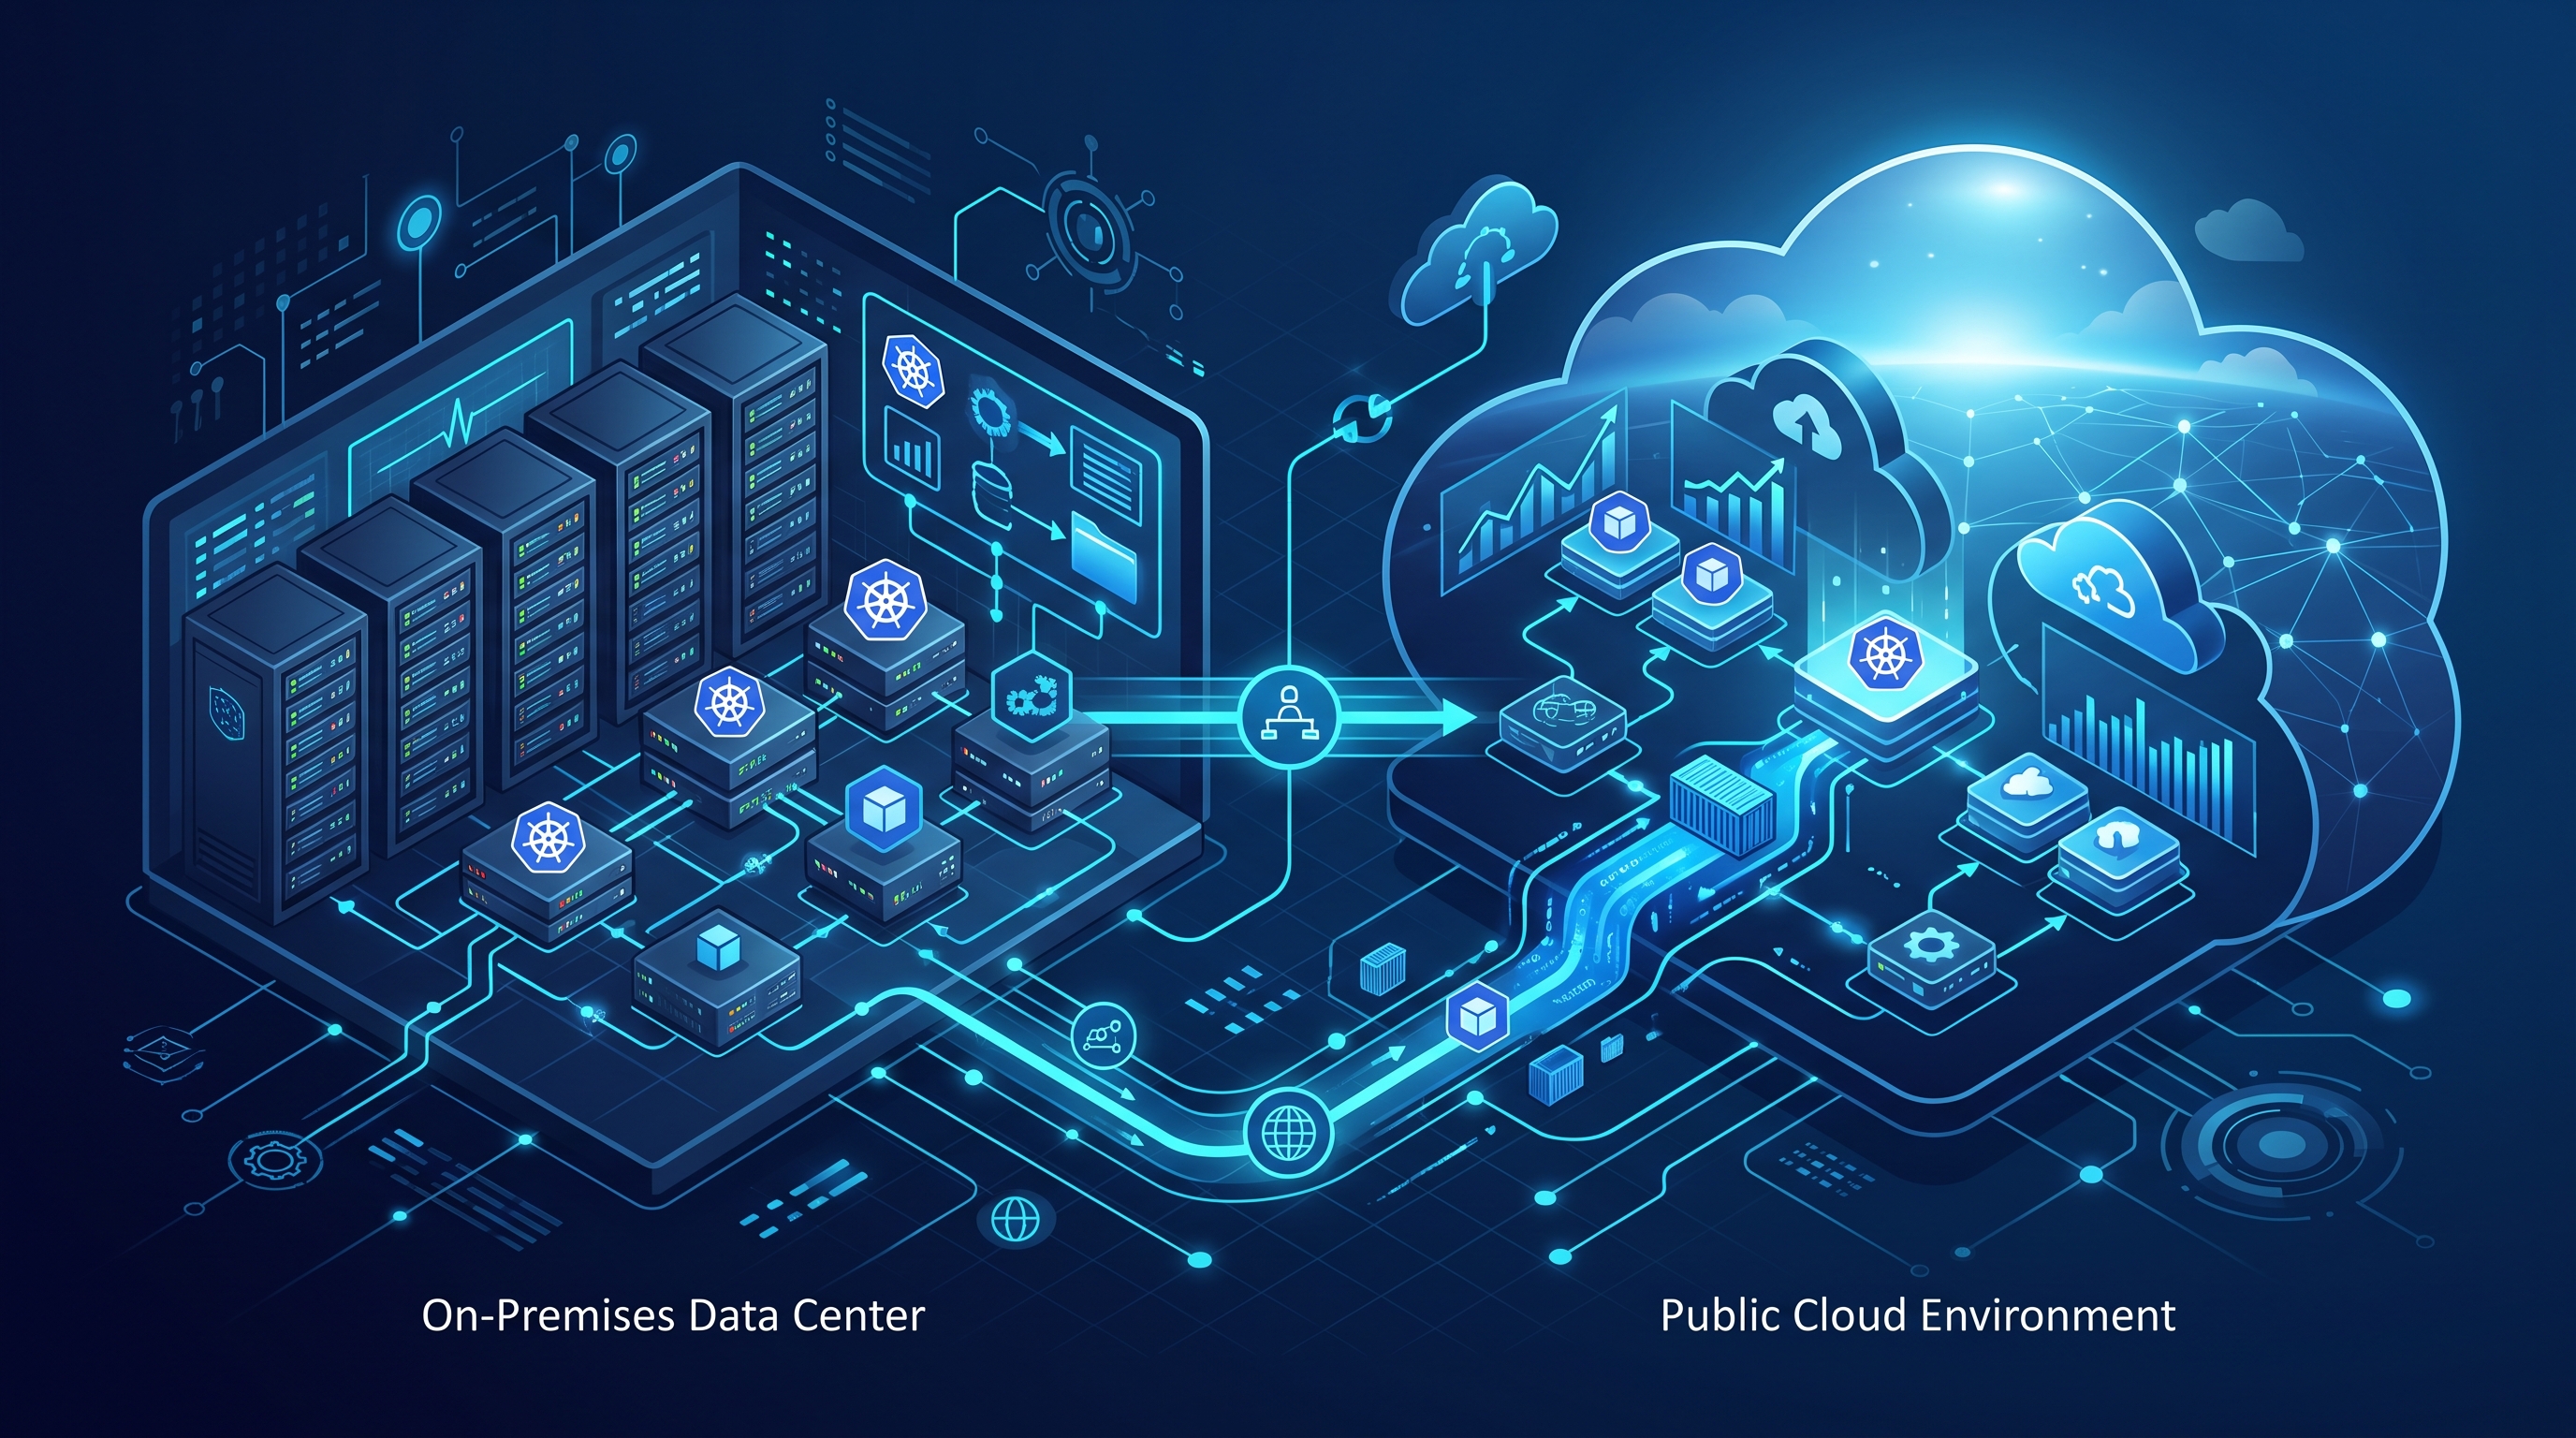
In my 25 years at institutions like JPMorgan Chase and Deutsche Bank, I have watched infrastructure budgets spiral out of control during peak trading hours or end-of-quarter reporting cycles. The old model of provisioning for peak capacity resulted in massive idle resources during quiet periods. By 2026, the narrative has shifted from "lift and shift" to intelligent, dynamic scaling. We are no longer just talking about static hybrid setups; we are talking about hybrid kubernetes cloud bursting 2026 architectures that seamlessly offload non-critical or volatile workloads to the public cloud while keeping sensitive data on-premises.
The biggest misconception I see in enterprise architecture reviews is the belief that cloud bursting requires a complete rewrite of the application stack. It does not. However, it does require a rigorous approach to state management, network topology, and security policy synchronization. If you treat the cloud as just another datacenter, you will fail. You must treat it as a distinct resource pool with different latency characteristics and cost structures.
The Architecture of Multi-Cluster Bursting
To implement cloud bursting effectively, you need a unified control plane that can manage resources across distinct boundaries. In 2026, we rely heavily on multi-cluster management platforms rather than ad-hoc scripts. Tools like Rancher, Red Hat OpenShift GitOps, or CNCF-certified solutions like Cluster API allow you to define a "fleet" of clusters where policies are inherited from a central hub.
The core principle is workload separation. You classify your applications into tiers:
- Stateful/Critical: Databases, core ledger systems. These stay on-premises.
- Stateless/Compute-Intensive: Batch processing, CI/CD runners, analytics. These burst to the cloud.
- Hybrid: Microservices that span both environments via service mesh.
For the stateless tier, you utilize Horizontal Pod Autoscalers (HPA) and Vertical Pod Autoscalers (VPA) that are aware of the underlying node pool costs. When the on-premises cluster hits 80% CPU utilization, the orchestrator should trigger a burst to the cloud. This isn't just about scaling out; it's about scaling *across*.
Network and Service Mesh Integration
Latency is the enemy of cloud bursting. If your on-premises application calls a service in the cloud with 200ms latency, the user experience degrades, and your cost-per-request skyrockets due to network egress fees. This is where a service mesh like Istio or Linkerd becomes non-negotiable.
By implementing a mesh, you can define traffic routing rules that allow requests to failover to the cloud if the on-premises endpoint is saturated. More importantly, you can use local proxies to cache responses. However, you must ensure that your AI-native Kubernetes observability is robust enough to detect these latency spikes in real-time. Without precise metrics, you are flying blind.
You need to monitor:
- Network egress costs per namespace.
- Pod restart rates during burst events.
- Cross-cluster request latency.
Security and Policy Synchronization
Security cannot be an afterthought. When you burst workloads to AWS, Azure, or GCP, you are extending your security perimeter. In 2026, we use policy-as-code tools like OPA (Open Policy Agent) and Kyverno to enforce compliance. These policies must be synchronized across all clusters. If a pod is not allowed to run as root on-premises, it must not be allowed to run as root in the cloud burst cluster.
I have seen too many enterprises get hit with compliance violations because they assumed the cloud provider’s infrastructure handled security. It does not. You are responsible for the container runtime. Ensure that your agentic AI security sandboxing mechanisms are active in the burst environment to detect anomalies in real-time. If a bursted workload starts behaving like a cryptominer or exfiltrating data, your security agents must be able to terminate it immediately, regardless of which cloud provider hosts it.
Cost Governance and Auto-Scaling Triggers
Cloud bursting can destroy your budget if left unchecked. You need hard limits. Implement budget alerts that trigger a "stop burst" command if costs exceed a certain threshold. Use Kubernetes Cost Allocation tags to track every pod.
Here is a practical checklist for implementing cost controls:
- Set maximum burst limits per namespace (e.g., no more than 50 pods).
- Implement spot instances for non-critical burst workloads to reduce costs by up to 70%.
- Use reserved instances for baseline capacity to stabilize base costs.
- Monitor egress data transfer costs, which often exceed compute costs.
Practical Implementation Steps
I have deployed similar architectures for financial institutions, and the process is always iterative. Start with a non-critical batch job. Use a tool like Karpenter or Cluster Autoscaler to manage the node lifecycle. Here is the sequence I recommend:
- Deploy the Hub: Set up your primary management cluster with GitOps integration.
- Sync Policies: Ensure OPA/Kyverno policies are identical across all clusters.
- Configure Mesh: Set up Istio or Linkerd for cross-cluster traffic management.
- Test Burst: Simulate load using tools like k6 or Locust to trigger auto-scaling.
- Monitor: Review metrics and adjust thresholds based on actual performance.
For those looking to deepen their expertise in managing these complex environments, I highly recommend reading our guide on AI-Powered GitOps Kubernetes Automation 2026. It covers the automation pipelines that make multi-cluster management feasible at scale.
Frequently Asked Questions
Q: Can I burst stateful workloads to the cloud? A: Generally, no. Stateful workloads require low-latency access to persistent storage. While some cloud providers offer managed databases, the complexity of syncing data between on-premises and cloud storage often outweighs the benefits. Stick to stateless microservices and batch jobs for bursting.
Q: How do I handle data sovereignty when bursting? A: You must ensure that the bursted workloads do not process or store sensitive data. Use data masking or tokenization before sending data to the cloud. Your security policies should explicitly forbid any persistent storage volumes in the burst namespace.
Q: Is cloud bursting only for large enterprises? A: No. With the democratization of Kubernetes, even mid-sized companies can benefit. However, the initial setup cost is higher. If you have fewer than 100 nodes, the operational overhead of multi-cluster management might not be worth it.
Q: What happens if the cloud provider goes down? A: This is why you never rely on a single cloud. Use a multi-cloud strategy or ensure you have enough on-premises capacity to handle the overflow. Your advanced Kubernetes certifications should include training on disaster recovery planning for hybrid environments.
Conclusion
Hybrid Kubernetes cloud bursting is not a silver bullet, but it is a powerful tool for managing variable workloads. By focusing on multi-cluster management, service mesh integration, and strict security policies, you can achieve the flexibility of the cloud without the risk. Start small, automate relentlessly, and always keep an eye on your costs. For more insights on navigating the complex landscape of enterprise Kubernetes, check out our article on Advanced Kubernetes Certifications Guide 2026.