
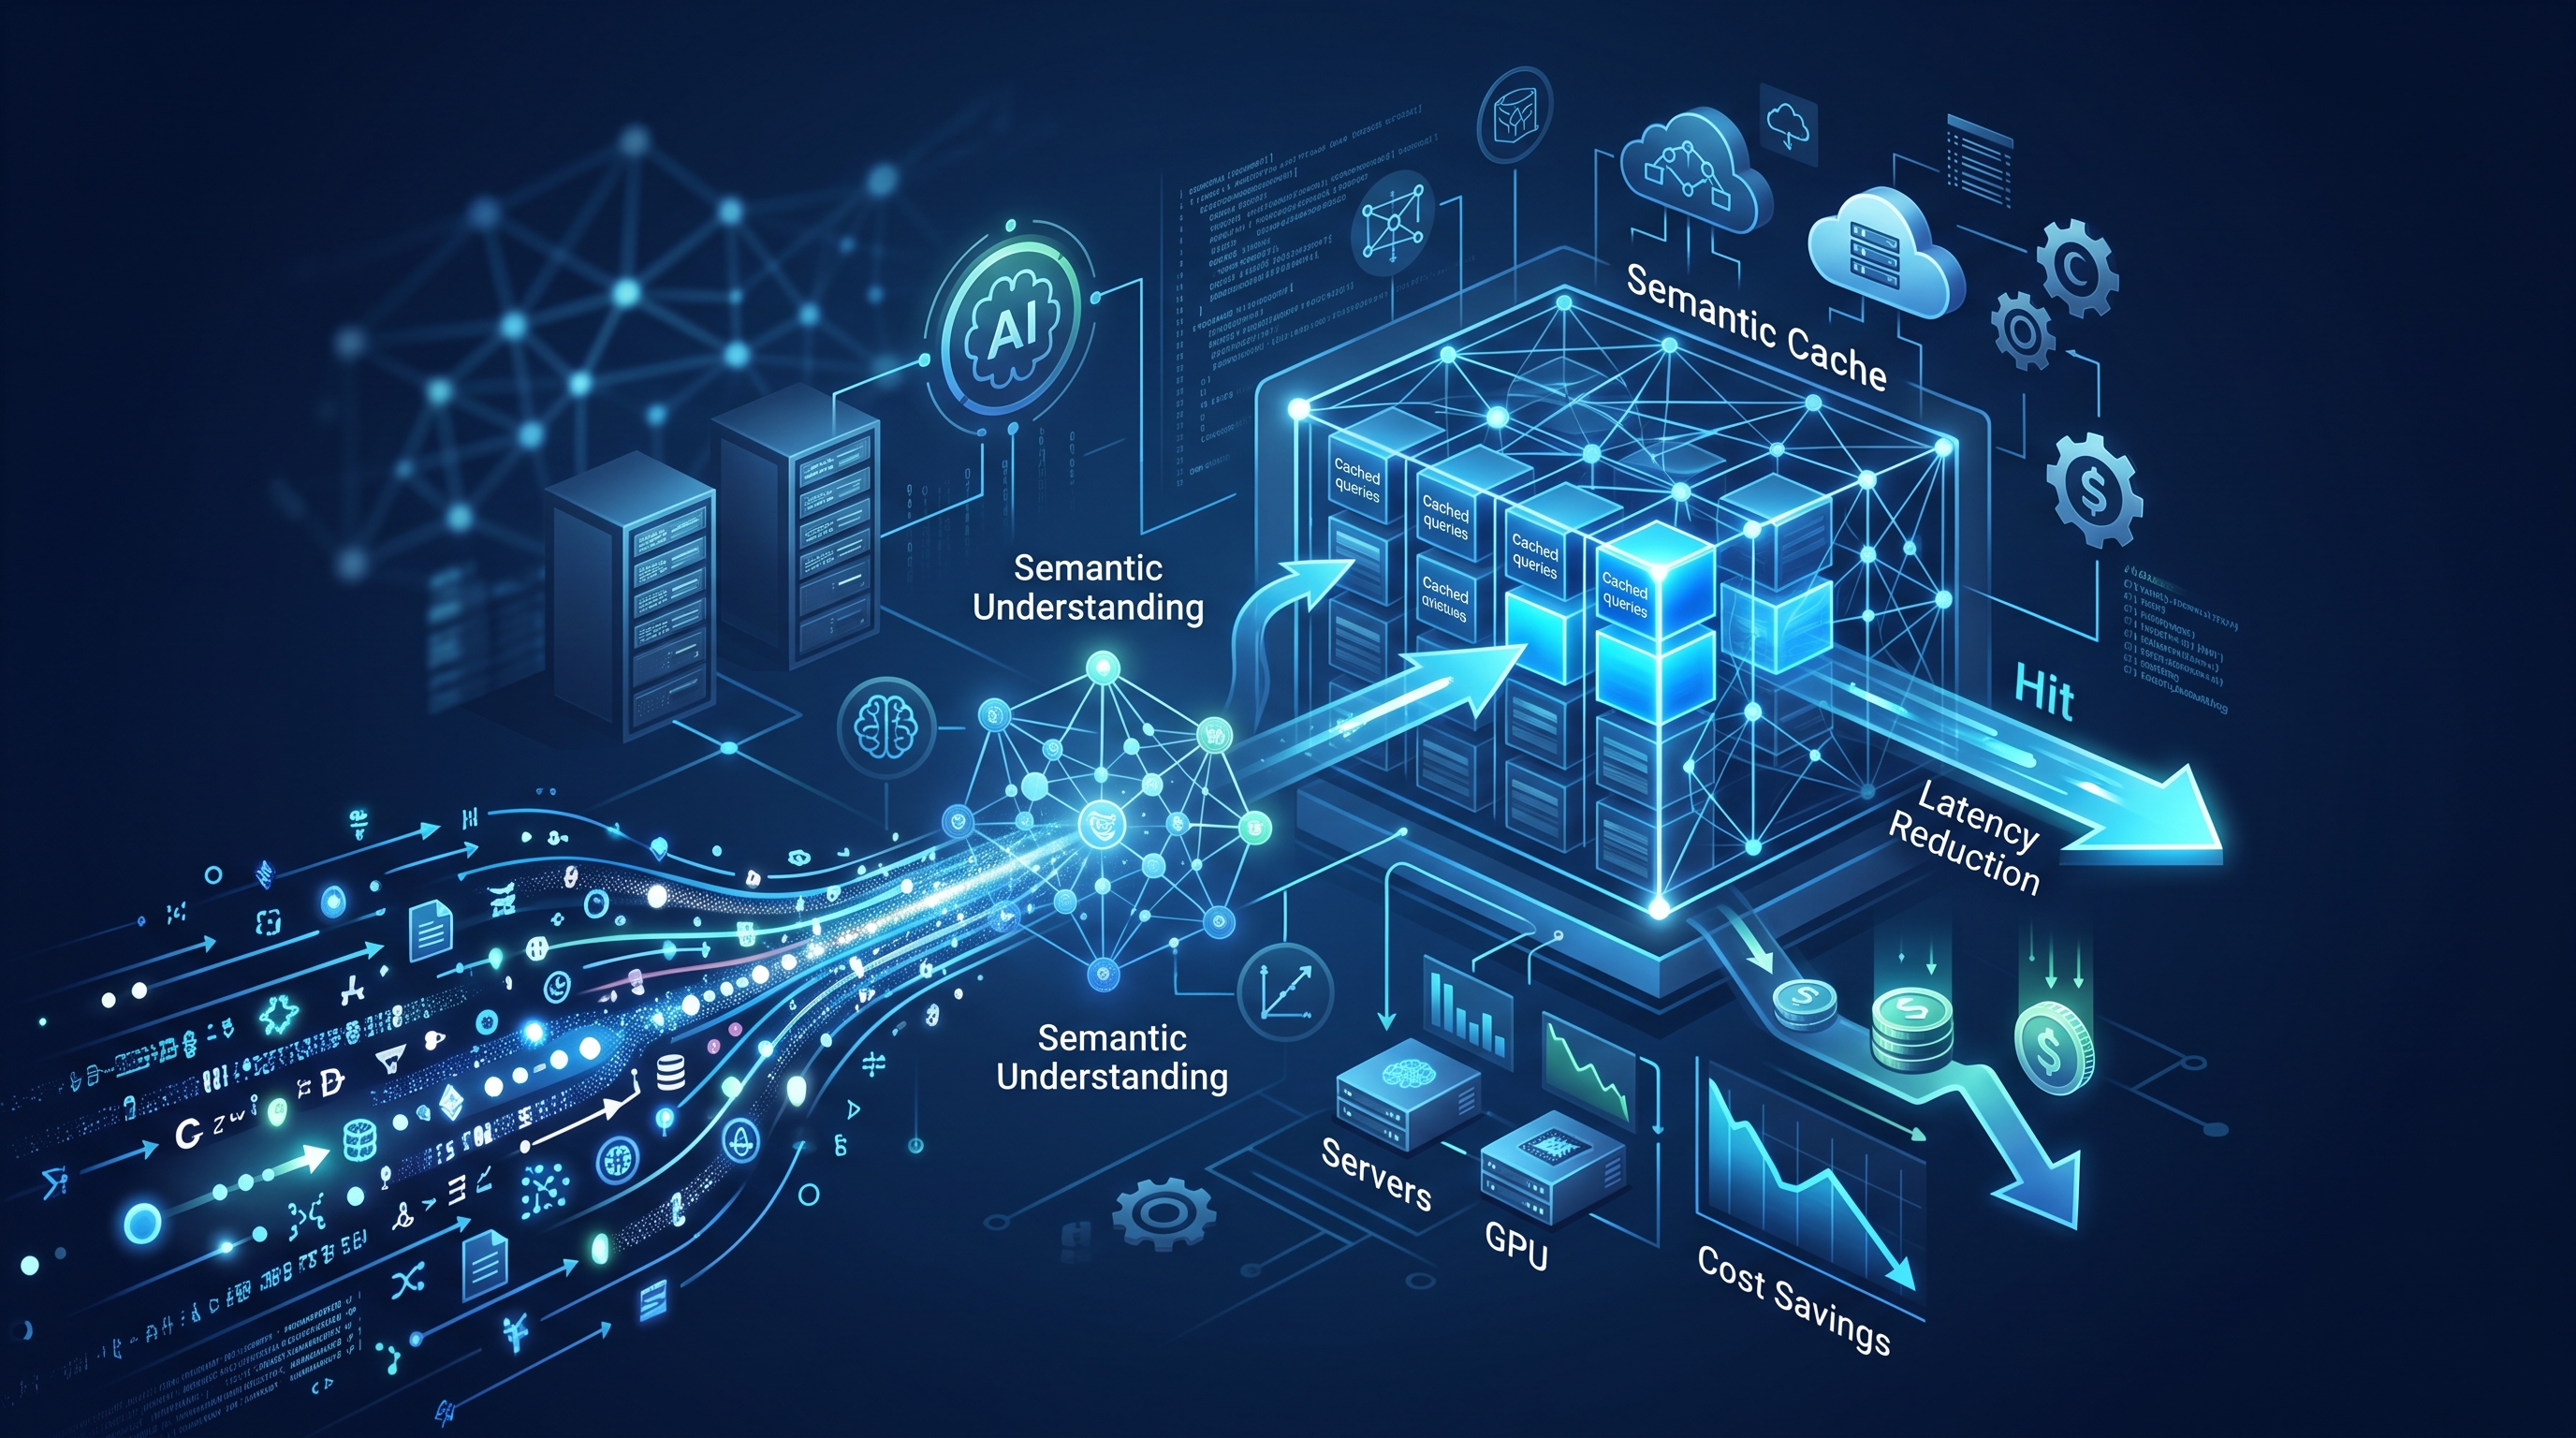
The 2026 Reality: Why Raw Inference Is Unsustainable
I’ve spent the last quarter reviewing infrastructure bills for several Fortune 500 clients, and the trend is undeniable: LLM inference costs are eating into margins faster than we anticipated. In 2024, we treated LLMs as novelty experiments. In 2026, they are the backbone of customer support, code generation, and internal knowledge retrieval. The problem? The variance in request patterns. Even with robust LLM cost optimization strategies, you cannot afford to pay for full token generation on every single query when 60-70% of those queries are repetitive or near-duplicates.
Semantic caching is the answer, but it is not a simple Redis key-value lookup. It is a sophisticated pipeline involving vector embeddings, similarity search, and strict governance. If you are still relying on exact string matching for caching, you are leaving money on the table. In a typical enterprise environment, we see semantic caching achieve hit rates between 40% and 60% for internal knowledge bases, directly translating to a proportional reduction in API tokens and GPU compute time.
Architecture: How Semantic Caching Actually Works
Let’s strip away the marketing fluff. A functional semantic cache sits between your application and the LLM provider. The flow is deterministic:
- Embedding Generation: The incoming user query is passed through a lightweight embedding model (often a 7B-8B parameter model running on CPU or low-GPU utilization).
- Vector Search: The resulting vector is compared against a vector store (like Pinecone, Weaviate, or a local Redis Vector Index) to find the N most similar historical queries.
- Similarity Scoring: A cosine similarity score is calculated. If the score exceeds your defined threshold (typically 0.85-0.92), the cache is considered a "hit."
- Response Retrieval: The previously generated answer is returned instantly, bypassing the LLM entirely.
If the similarity score is below the threshold, the request proceeds to the LLM. Crucially, the new query and response are then embedded and stored in the cache for future use. This creates a self-improving loop where your cache becomes more accurate over time as it learns the nuances of your specific user base.
Latency and Cost: The Quantifiable Impact
In my experience deploying these systems on Kubernetes clusters, the latency reduction is immediate and dramatic. A standard LLM inference call, even with optimized serving, takes between 2 to 5 seconds for a moderate-length response. A semantic cache hit, however, typically returns in under 100 milliseconds. This is a 20x to 50x improvement in user-perceived latency.
Cost savings are equally stark. Consider a customer support bot processing 10,000 queries per hour. If 50% of those queries are semantic duplicates, you are effectively doubling your infrastructure load for no value. By implementing semantic caching, you reduce the actual inference calls by half. For a model priced at $10 per million tokens, this is not just a marginal saving; it is a fundamental shift in your unit economics. Furthermore, by reducing the load on the primary model, you can downsize your GPU instances or use smaller, cheaper models for the 50% of queries that are truly unique, while reserving the expensive, high-capacity models for complex, novel reasoning tasks.
Implementation Patterns: Where to Place the Cache
Placement is critical. I have seen teams place the cache at the application layer, at the API gateway, or as a sidecar to the LLM service. Each has trade-offs:
- Application Layer: Easiest to implement but duplicates the embedding logic across multiple services. Hard to maintain consistency.
- API Gateway: Centralized control. You can apply policies and quotas here. Best for external-facing APIs. Integrates well with gateway routing strategies.
- Sidecar Proxy: The most robust enterprise pattern. The sidecar intercepts traffic, performs the embedding and search, and passes only misses to the main LLM container. This keeps the LLM container lean and focused on inference.
For enterprise deployments, I strongly recommend the sidecar or gateway approach. It decouples the caching logic from the business logic, allowing you to update the embedding model or similarity thresholds without redeploying your core application.
Pitfalls and Governance: Avoiding Cache Poisoning
Semantic caching is not a "set and forget" feature. The biggest risk is cache poisoning or stale data. If your underlying knowledge base changes, old cached responses become incorrect. You must implement a Time-To-Live (TTL) mechanism, but TTL alone is insufficient. You need versioning. Each cache entry should be tagged with a version of the system prompt and the underlying knowledge base.
Furthermore, you must monitor for "similarity drift." As user language evolves, the embedding space shifts. Regularly audit your cache hit rates. If hits drop below 30%, your threshold might be too strict, or your embedding model might be misaligned with your domain. Implement a fallback mechanism: if the cache confidence is low (e.g., 0.75-0.85), you might still return the cached answer but append a disclaimer or route it for human review.
Also, consider the cost of the embedding model itself. While cheaper than the LLM, it is not free. Ensure that the cost of generating the embedding is less than the cost of the potential LLM call it avoids. In most cases, this is a non-issue, but for very short queries, the overhead can be significant.
Looking Ahead: Agentic AI and Semantic Caching
As we move into agentic workflows, where LLMs perform multi-step reasoning, semantic caching becomes even more powerful. Agents often repeat sub-tasks. Caching the output of intermediate steps can drastically reduce the total token count. However, this requires a more granular cache that understands context windows and conversation history. The future of semantic caching is not just about storing answers, but about storing reasoning paths.
For now, focus on the low-hanging fruit: repetitive queries, FAQ sections, and code snippets. Implement a vector cache, set a sensible threshold, and monitor the results. The savings will be immediate, and the latency improvements will be felt by every user of your application.
Frequently Asked Questions
What is the ideal similarity threshold for semantic caching?
There is no one-size-fits-all number, but 0.85 to 0.92 cosine similarity is the industry standard for balancing accuracy and hit rate. Lower thresholds (0.75-0.80) increase hit rates but risk returning slightly off-topic answers. Higher thresholds (0.95+) are too strict and reduce the cache utility. Start at 0.85 and adjust based on your domain's sensitivity to error.
Does semantic caching work with multi-modal LLMs?
Yes, but it requires multi-modal embedding models. You must embed both the text query and any attached images or documents into a shared vector space. The complexity increases, but the potential for cost savings remains high, especially in domains like visual search or document analysis where duplicate queries are common.
How do I handle cache invalidation when the knowledge base updates?
Implement a versioning scheme for your knowledge base. When the KB updates, increment the version ID. Cache entries with the old version ID are either invalidated or marked as stale. You can also implement a soft invalidation where old entries are deprioritized but not immediately deleted, allowing for a smooth transition. Regular audits of cache freshness are essential.
Is the overhead of embedding generation worth the cost savings?
In almost all enterprise scenarios, yes. The cost of generating an embedding vector is typically 1-2% of the cost of a full LLM inference. Given that you can avoid 40-60% of LLM calls, the net savings are substantial. The only exception is extremely low-volume applications where the fixed cost of maintaining the vector database outweighs the variable savings.