
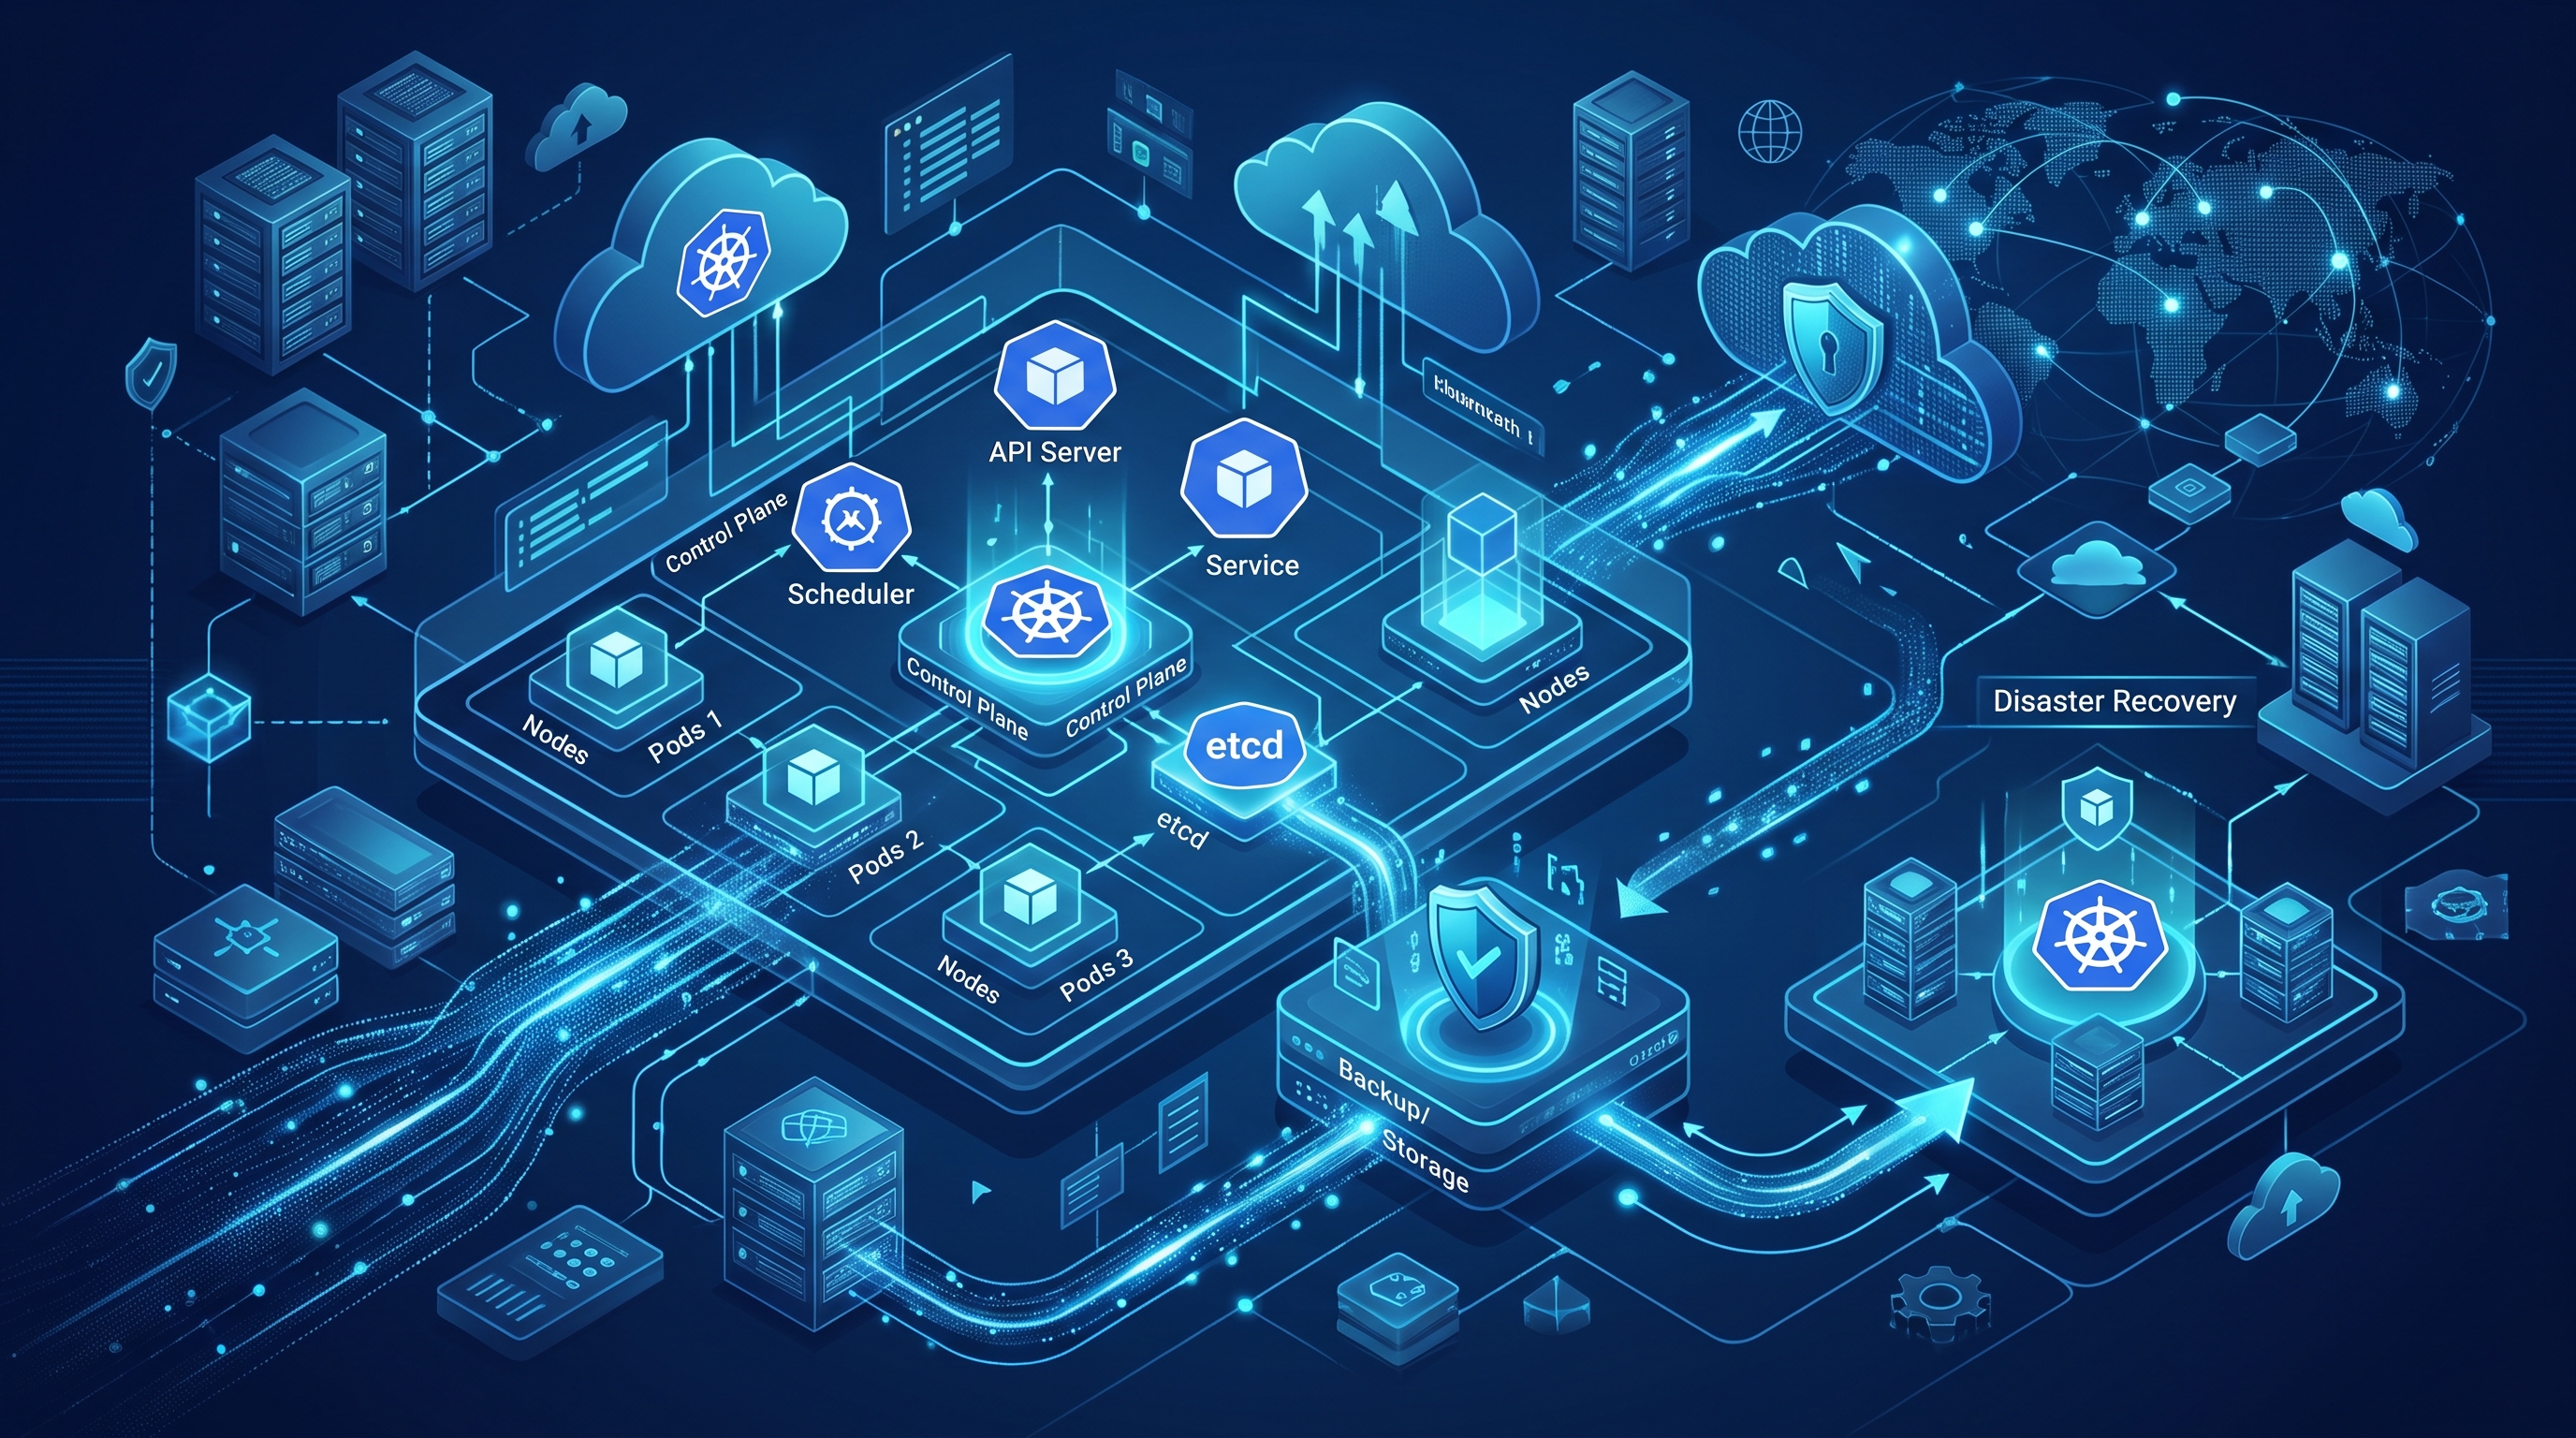
The Single Point of Failure
In my 25 years at institutions like JPMorgan Chase and Deutsche Bank, I have seen countless outages traced back to a single, quiet assumption: the control plane is resilient. It is not. In Kubernetes, etcd is the sole source of truth for the entire cluster state. There are no replicas of the state in the API server; the API server is stateless. If etcd data is corrupted, the cluster is effectively dead, regardless of how many worker nodes you have running.
Many engineers treat etcd as "infrastructure" and ignore it until disaster strikes. This is a career-ending mistake. By 2026, with the rise of agentic AI managing complex workloads, the attack surface and complexity of state management have increased. We cannot rely on manual, ad-hoc backups. We need deterministic, verified, and automated disaster recovery protocols. This post strips away the marketing fluff and gives you the operational reality of securing your etcd data.
Snapshotting: The Baseline of Safety
Backing up etcd is straightforward in theory but often botched in practice. The core command is `etcdctl snapshot save`. However, raw snapshots are only as good as the frequency and integrity of the backups. You must automate this process. Do not rely on cron jobs that might fail silently. Use a dedicated sidecar or a Kubernetes CronJob that runs `etcdctl` within the control plane nodes or a dedicated backup pod.
When you take a snapshot, you are capturing the full state of the cluster at that moment. This includes namespaces, deployments, secrets, and persistent volume claims. Crucially, you must also back up the etcd keys and certificates used for client authentication. If you lose these, you cannot restore the cluster, even with the data.
- Run snapshots at least every 15 minutes for critical financial or healthcare workloads.
- Store snapshots off-cluster. S3, GCS, or Azure Blob Storage are acceptable, but they must be versioned and encrypted.
- Implement a retention policy. Keep the last 7 daily snapshots and the last 30 weekly snapshots. This provides a rollback window for both accidental deletions and ransomware events.
I have seen clusters where snapshots were being taken but never verified. A backup that cannot be restored is not a backup; it is a false sense of security. You must regularly test the restore process in a staging environment that mirrors your production topology.
Compaction and Defragmentation
etcd is a key-value store that uses a versioned history. Every change to the cluster state creates a new revision. If you do not manage this history, the etcd database will grow indefinitely, leading to performance degradation and eventually, storage exhaustion. This is where compaction comes in.
Compaction removes the historical revisions of keys that are no longer needed. The default retention window for etcd revisions is 300 seconds (5 minutes). This is too short for most enterprise use cases, where you might need to rollback a deployment or configuration change that happened an hour ago. I recommend setting the `--auto-compaction-retention` flag to a value that balances your need for rollback history with storage efficiency. A common safe value is 1 hour.
However, compaction does not free up disk space immediately. It marks the revisions as compacted, but the physical space is not reclaimed until you defragment the database. Defragmentation is a write-heavy operation that can impact cluster performance if run during peak hours. Schedule defragmentation during maintenance windows or use the `etcdctl defrag` command with caution.
Neglecting compaction and defragmentation is a silent killer. I have seen etcd databases grow to gigabytes in size, causing API server latency to spike and leading to node evictions. Monitor the `etcd_server_has_leader` and `etcd_disk_wal_fsync_duration_seconds` metrics. If these metrics are rising, your etcd cluster is struggling, and it is likely due to unmanaged storage growth.
Disaster Recovery: The Restore Process
When disaster strikes—whether it is a datacenter outage, a catastrophic corruption event, or a cyberattack—the restore process must be executed with precision. The general steps are as follows:
- Stop the API Server and kubelet: This prevents new writes to the corrupted etcd cluster.
- Restore the Snapshot: Use `etcdctl snapshot restore` to replace the current etcd data directory with the snapshot.
- Restart etcd: Bring the etcd cluster back online with the restored data.
- Verify the Cluster: Check the status of the cluster using `etcdctl endpoint health` and verify that key resources are present.
- Restart the API Server and kubelet: Bring the control plane back online.
This process sounds simple, but in a multi-master setup, you must ensure that all etcd members are synchronized before restarting the API server. If you restart the API server against an etcd cluster that is still in a split-brain state, you will create more problems than you solve.
For high-availability setups, consider using a tool like `etcd-backup-restore` (EBR) from CoreOS. EBR provides a more robust framework for managing snapshots, backups, and restores, including support for incremental backups and cross-cluster replication. It is a standard tool in many enterprise environments and is worth integrating into your infrastructure.
Integrating with Modern Operations
In 2026, we are moving beyond manual operations. The integration of AI agents and GitOps workflows is changing how we manage Kubernetes. You should be looking at AI-powered GitOps for Kubernetes automation to ensure that your cluster state is always reconciled with your desired state. However, GitOps cannot recover from a lost etcd state. You need a separate, robust backup strategy.
Consider using AI agents to monitor etcd health and trigger alerts when compaction or defragmentation is needed. These agents can also automate the backup process, ensuring that snapshots are taken and stored correctly. This reduces the operational burden on your team and ensures that your disaster recovery plan is always up to date.
Furthermore, as you explore AI agents in enterprise Kubernetes, remember that these agents will generate significant state changes. Your etcd backup strategy must be able to handle the increased volume of writes. Monitor the write latency and adjust your backup frequency accordingly.
Frequently Asked Questions
How often should I backup etcd?
For critical production workloads, backup every 15 minutes. For less critical environments, every hour is acceptable. The key is to align the backup frequency with your Recovery Point Objective (RPO). If you can tolerate losing 15 minutes of data, backup every 15 minutes. If you can tolerate losing 1 hour, backup every hour. Do not guess; define your RPO and automate accordingly.
Can I restore etcd from a snapshot taken on a different Kubernetes version?
No. You must restore the snapshot to an etcd cluster running the same version as the one it was taken from. If you upgrade your Kubernetes cluster, you must also upgrade etcd in a controlled manner. Restoring a snapshot from a newer version to an older version will result in data corruption and cluster failure.
What is the difference between compaction and defragmentation?
Compaction removes the historical revisions of keys, freeing up logical space. Defragmentation reclaims the physical disk space used by the compacted revisions. You must perform both operations to effectively manage etcd storage. Compaction alone will not reduce the disk usage; defragmentation is required to actually free up space.
Is it safe to defragment etcd during peak hours?
No. Defragmentation is a write-heavy operation that can cause significant latency spikes in the API server. It is recommended to perform defragmentation during maintenance windows or when cluster load is low. Monitor the `etcd_disk_wal_fsync_duration_seconds` metric to determine the best time for defragmentation.